
Page 1 failed to load.
LoRAtech - ComfyUI Hub - AI Influencer Master Class - H3 REF2V Face Refine Xtra HD
 Up next
Stickyspoodge - The Hole
About This Title
Wide shots are where AI influencer videos fall apart. The moment your character is small in the frame, MiniMax H3 smears her eyes and mouth, or swaps her for a stranger. This workflow fixes the face on every single frame, so the far-away shots finally look like her.
What you can do with itWide lifestyle shots that look like her. Beach, rooftop, street, gym: the whole scene in frame, her face still sharp.
Walk-up shots. She starts far away and walks to the camera, and her face holds up the whole way.
Talking from across the room. She can say her line from far away and the mouth still follows the audio.
Same girl in every clip. Your portrait reference locks her face, so a whole feed of videos stays consistent.
Extra HD. A two-pass render with a latent upscale for more detail than a single pass.
Members get the workflow, a gallery of before and after video examples, the exact prompts behind every one, and my tips for getting clean faces on the first try.
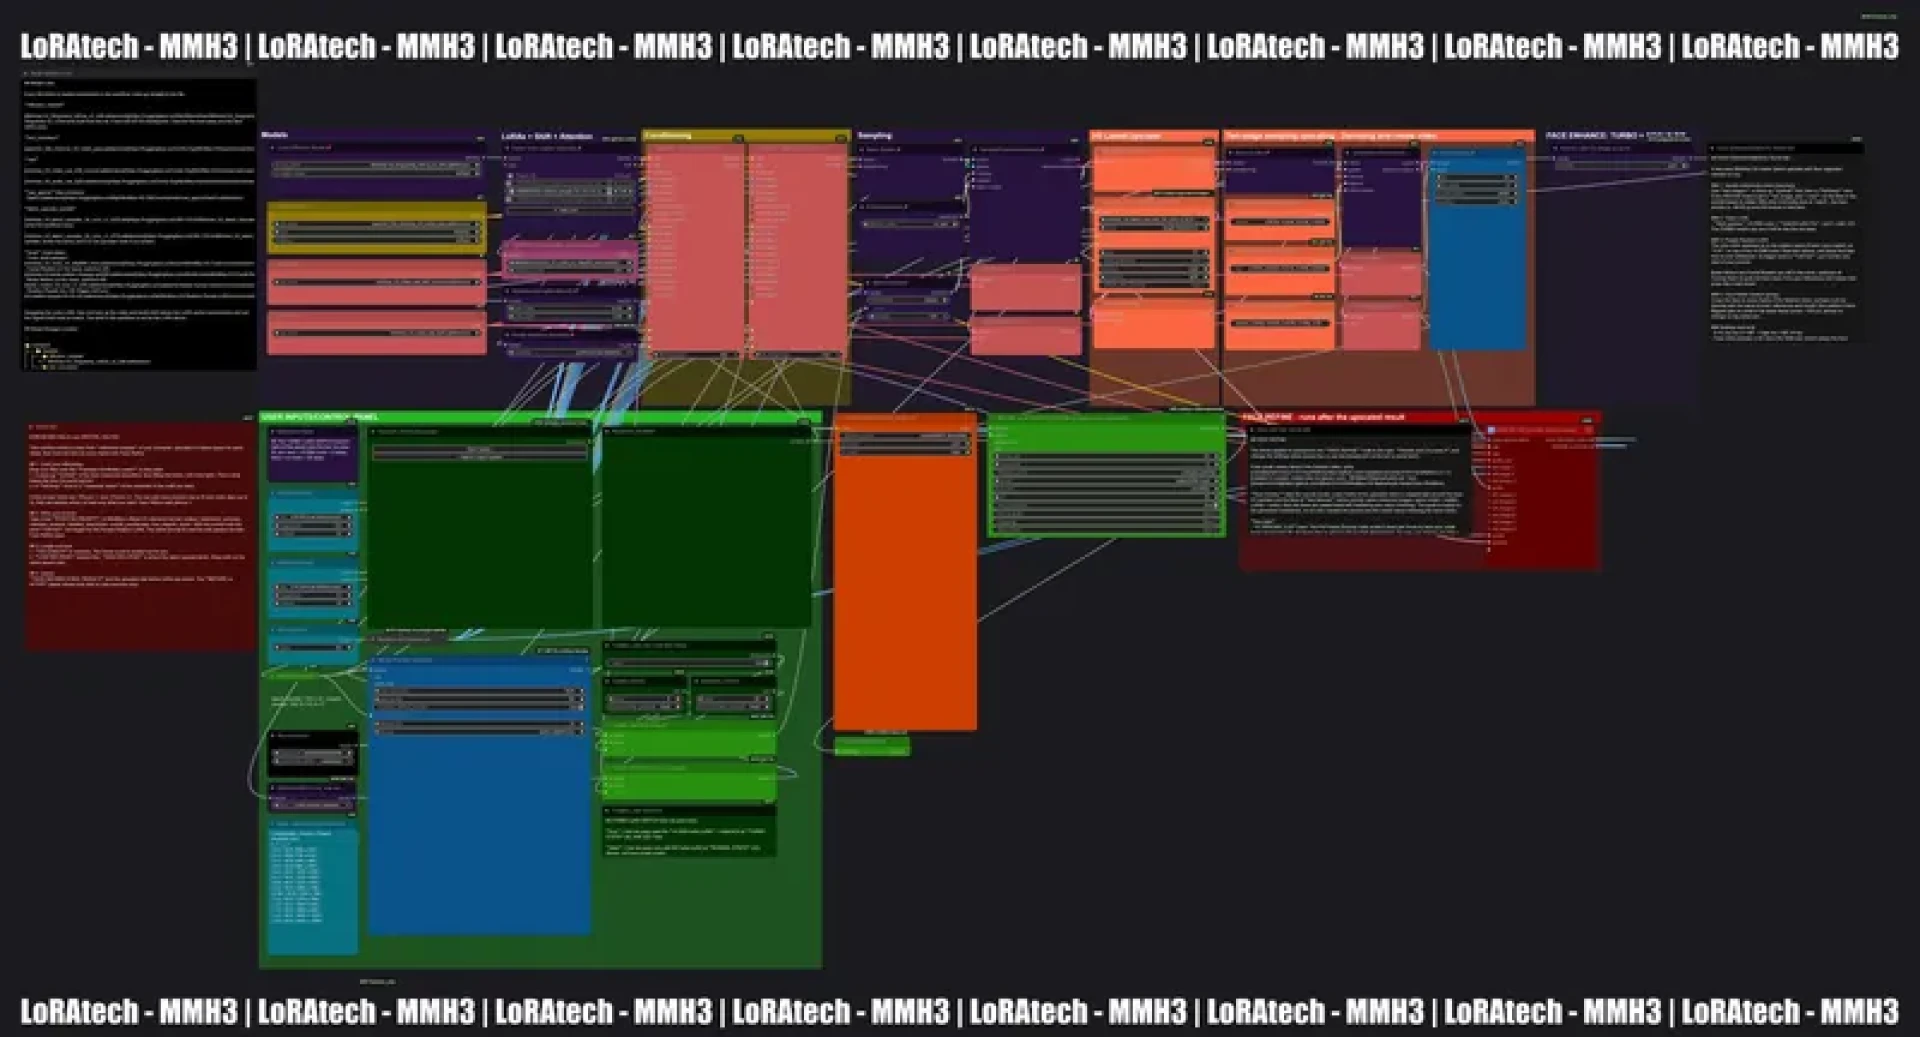
Everything you need is inside the workflow. Every model download link, which folder each file goes in, the custom nodes to install and step by step instructions are in the notes on the left side of the workflow. Open them, read them top to bottom, and you're set up. Update ComfyUI first: the Singularity model and the nvfp4 text encoder need a recent build with native MiniMax H3 support.
Want to zoom in? The full-size screenshot is attached to this post as well.
How to use it, step by stepThis one has more moving parts than my other workflows, so here's the whole run, in the order you'll touch things. The numbers on the screenshots match the steps.
Load your two refs. Drop them on the Fantastic H3 Media Loader: the close-up portrait first, then the full-body shot in the outfit and place you want. The order in the loader is the number in your prompt, so the portrait is <Picture 1> and the body shot is <Picture 2>. Drag them around to change it.
Paste your prompt into POSITIVE PROMPT. Start it with r34l1sm and write it in MiniMax's reference format. The easiest way is to copy one of my prompts below and swap the scene.
Set the length and size. VID LENGTH is in seconds; the frame count is worked out for you. LOW RES PASS (0.4 MP) and HIGH RES PASS (1 MP) set the aspect ratio. Keep both on the same ratio.
Pick turbo or quality. TURBO LoRA ON LOW RES PASS on true runs the first pass in 6 fast steps. False runs it with no turbo at 20 steps: slower, full base model quality. The high res pass always uses the turbo.
Leave the LoRA stack as it is. Only People Realism is on, at 0.8. Better Motion and Facial Realism are there, switched off. Turning them on pulls her face away from your refs and makes fast props smear.
The turbo LoRA (v4 EMA) runs both passes at 1.0. If you ever swap it, set the Sigma Shift to whatever the new LoRA's author recommends.
Face Refine runs by itself after the main render. Double-click the node to open its settings. The one dial worth knowing is DENOISE (0.40). If her face barely changes, raise it a little. If her head starts to drift against her body, lower it.
Your results. FACE REFINED (FINAL RESULT) saves to video/MMH3_facerefine, and the same clip before refine saves to video/MMH3_facerefine_orig. The BEFORE vs AFTER player shows both side by side so you can check the fix; it's a preview and isn't saved.
How it worksTwo references. Load a close-up portrait first (<Picture 1>), then a full-body shot of her in the outfit and place you want (<Picture 2>). Both are read at full size (ref_image_size = max), so H3 actually sees the details of her face.
Low res pass, then a latent upscale. The video is drawn at 0.4 MP, upscaled in latent space and finished at 1 MP. That's where the extra detail in the whole frame comes from.
Face Refine. After the render, every frame is cropped tight around her face, H3 redraws just the face at low denoise with the same prompt, refs and model, and it's pasted back with soft edges and matched color. The audio is locked, so her mouth keeps following the same line.
Both versions get saved: video/MMH3_facerefine is the final result and video/MMH3_facerefine_orig is the same clip before Face Refine. The BEFORE vs AFTER player in the workflow shows them side by side.
What's insideFantastic H3 Media Loader for your refs. Drag the order around to change which one is Picture 1.
The Singularity V2 model with the v4 EMA turbo LoRA and the AdaLN fix on both passes, 6 steps on the low res pass.
A turbo switch. On = fast 6-step low res pass. Off = no turbo, 20 steps, slower but full base model quality.
The People Realism LoRA at 0.8 on top of the turbo, the same pairing as the most realistic skin setups. Better Motion and Facial Realism sit in the stack too, switched off.
The H3 latent upscaler between the two passes.
Face Refine packed into one node at the bottom. Double-click it to open the settings.
How I made each exampleDefault settings on every one, 6 seconds each. The top zoom is the clip straight out of the render, the bottom zoom is the same frame after Face Refine. The orange box on the full shot shows where the zoom is from.
1. Smeared face, fixedShe waves from the far end of the beach, then jogs toward the camera. In the main render her eyes and mouth melt into a smear while she's small in the frame. Face Refine redraws the face on every frame from your portrait ref, so she's the same girl the whole clip, and her mouth still follows the line she says.
Refs: Picture 1 is a close-up portrait, Picture 2 is the far-away shot in the same outfit and place. Both made with Krea 2 and the same character LoRA.
Tip: Ask for a little movement toward the camera. The face grows over the clip, and Face Refine scales its strength down as the face gets bigger, so the close end stays untouched while the far end gets fixed.
The exact prompt:
r34l1sm subject_definitions: <Picture 2> is the first frame of [Shot 1], showing <Subject 1> standing far away at the edge of the water on a white-sand beach, waving at the camera. <Subject 1> is the young woman in <Picture 1> and <Picture 2>: her face, eyes, skin and hair come from the close-up in <Picture 1>, and her outfit comes from <Picture 2>, a black triangle bikini with thin straps, barefoot, bare wrists and bare ears. summary: [keyframe completion] The target video starts from <Picture 2> and shows <Subject 1> waving from the waterline of a tropical beach, calling out to the camera, then jogging a few playful steps toward it through the shallow foam. retention_analysis: <Picture 1> (identity reference for <Subject 1>): fully_preserved - the exact same face, facial structure, eyes, nose, lips, skin tone and hair as in <Picture 1>. <Picture 2> ([Shot 1] first frame): fully_preserved - the beach, the sea, the light, her bikini and her pose open the clip exactly as in the image. <Subject 1> (appears in [Shot 1]): fully_preserved - her face matches <Picture 1> and her outfit matches <Picture 2> for the whole video. detailed_description: The target video is casual vertical phone footage filmed by a friend standing still on the dry sand, bright late-morning sunlight, turquoise water, natural colours. [Shot 1] The shot begins from <Picture 2>: a static wide shot frames a long white-sand beach with footprints in the foreground and <Subject 1> small in the frame at the edge of the water, waving with a big smile. She keeps waving, cups one hand by her mouth and calls out, <d>[English] Come in, the water's so warm!</d>, then laughs and jogs a few playful steps toward the camera along the waterline, small splashes of foam around her ankles, her hair bouncing in the breeze, growing a little larger in the frame while the camera holds still. Gentle waves roll in behind her. overall_soundscape: Soft waves washing onto the sand, a warm sea breeze, distant seabirds, light splashes as she jogs through the shallow water, her voice carried from a distance with a bright laugh. non_diegetic_music: none
2. Golden hour, clean faceA wide shot across a rooftop terrace at sunset, the kind of shot every lifestyle account posts. Warm low light is where H3 usually loses the eyes. Face Refine keeps them sharp while she talks and walks.
Refs: Picture 1 is a close-up portrait, Picture 2 is the far-away shot in the same outfit and place. Both made with Krea 2 and the same character LoRA.
Tip: Keep the light on her face soft in your refs (a thin veil of cloud, golden hour). Hard midday sun on the portrait ref carries straight into the refined face as shine.
The exact prompt:
r34l1sm subject_definitions: <Picture 2> is the first frame of [Shot 1], showing <Subject 1> standing far away at the glass railing of a rooftop terrace at golden hour. <Subject 1> is the young woman in <Picture 1> and <Picture 2>: her face, eyes, skin and hair come from the close-up in <Picture 1>, and her outfit comes from <Picture 2>, a fitted black satin slip dress with thin straps and black strappy heels, bare wrists and bare ears. summary: [keyframe completion] The target video starts from <Picture 2> and shows <Subject 1> at the far end of a rooftop terrace at sunset, greeting the camera with a teasing line, then walking slowly toward it past the lounge sofas. retention_analysis: <Picture 1> (identity reference for <Subject 1>): fully_preserved - the exact same face, facial structure, eyes, nose, lips, skin tone and hair as in <Picture 1>. <Picture 2> ([Shot 1] first frame): fully_preserved - the terrace, the skyline, the warm light, her dress and her pose open the clip exactly as in the image. <Subject 1> (appears in [Shot 1]): fully_preserved - her face matches <Picture 1> and her outfit matches <Picture 2> for the whole video. detailed_description: The target video is casual vertical phone footage filmed by a friend standing still by the rooftop door, warm golden-hour light, a glowing city skyline, natural colours. [Shot 1] The shot begins from <Picture 2>: a static wide shot frames a long stone-tiled rooftop terrace with lounge sofas and olive trees in the foreground and <Subject 1> small in the frame at the far glass railing, one hand resting on it. She lifts her hand off the railing, tilts her head with a slow flirty smile and says, <d>[English] You're late... but this view makes up for it.</d>, then walks slowly toward the camera down the middle of the terrace, one foot in front of the other in her heels, the satin dress catching the warm light, growing a little larger in the frame while the camera holds still. The skyline glows behind her. overall_soundscape: A soft evening breeze on the rooftop, a distant murmur of city traffic far below, the light click of her heels on the stone tiles, her voice carried softly from a distance. non_diegetic_music: none
3. Tiny in the frame, still herShe stands behind the far baseline, a small figure across the whole court. Without Face Refine her face comes out smeared and generic. With it, the face matches your portrait ref.
Refs: Picture 1 is a close-up portrait, Picture 2 is the far-away shot in the same outfit and place. Both made with Krea 2 and the same character LoRA.
Tip: Keep small, fast props still. A flying tennis ball is one of the hardest things for H3 in a wide shot, so here the ball rests in her hand for the whole clip, and the prompt says so.
The exact prompt:
r34l1sm subject_definitions: <Picture 2> is the first frame of [Shot 1], showing <Subject 1> standing far away behind the opposite baseline of an outdoor tennis court, holding a racket and a tennis ball. <Subject 1> is the young woman in <Picture 1> and <Picture 2>: her face, eyes, skin and hair come from the close-up in <Picture 1>, and her outfit comes from <Picture 2>, a fitted white sleeveless tennis crop top, a white pleated tennis skirt, a white sun visor and white tennis shoes, bare wrists and bare ears. summary: [keyframe completion] The target video starts from <Picture 2> and shows <Subject 1> on the far side of a tennis court, holding a tennis ball still in her hand, teasing the camera, then walking up toward the net with a cheeky grin. retention_analysis: <Picture 1> (identity reference for <Subject 1>): fully_preserved - the exact same face, facial structure, eyes, nose, lips, skin tone and hair as in <Picture 1>. <Picture 2> ([Shot 1] first frame): fully_preserved - the court, the net, the fence, the sunlight, her outfit and her pose open the clip exactly as in the image. <Subject 1> (appears in [Shot 1]): fully_preserved - her face matches <Picture 1> and her outfit matches <Picture 2> for the whole video. detailed_description: The target video is casual vertical phone footage filmed by a friend standing still behind the near baseline, bright afternoon sunlight, a blue hard court, natural colours. [Shot 1] The shot begins from <Picture 2>: a static wide shot frames the blue court with crisp white lines and the low net in the foreground and <Subject 1> small in the frame behind the far baseline, holding her racket in one hand and a yellow ball resting still in the other hand, the ball staying in her hand for the whole video. She points her racket at the camera with a cheeky grin and calls out, <d>[English] Ready to lose?</d>, then laughs and walks toward the net with a confident stride, her skirt swaying, growing a little larger in the frame while the camera holds still. The green fence and trees stand behind her. overall_soundscape: A light breeze through the trees, distant birdsong, the squeak of her tennis shoes, her voice carried from across the court with a playful laugh. non_diegetic_music: none
Quick rules that save you re-rollsPortrait first. Picture 1 has to be a close-up where her face fills the frame in soft, even light. Face Refine copies this face.
Start every prompt with r34l1sm. That's the trigger word for the People Realism LoRA. Without it the LoRA barely does anything.
Use MiniMax's official reference format (subject_definitions, summary, retention_analysis, detailed_description, overall_soundscape, non_diegetic_music). Copy one of my prompts above and swap the scene.
Describe what you want, not what you don't. H3 has no negative prompt, so "bare ears" works and a "no earrings" line can backfire.
One person per shot. Face Refine fixes the largest face. For two people, run it once per person.
Face Refine helps most on small faces. On a big close-up it barely changes anything, and that's on purpose.
Short on VRAM? Lower VID LENGTH first. Full-size refs and the refine pass both add memory.
Huge credit to Carasibana for ComfyUI-H3-FaceRefine, Shrek3OnVH5 for the native audio lock node, PlagueKind for the AdaLN LoRA fix, larryvrh for the v4 EMA turbo LoRA, LBH-123-AI for the H3 latent upscaler, WarmBloodAban for Singularity V2, and the authors of the realism LoRAs (prithivMLmods, vpakarinen and fal). Links are in the workflow note.
The workflow file is attached below. Drop it into ComfyUI, read the notes, and have fun with it.
Wide shots are where AI influencer videos fall apart. The moment your character is small in the frame, MiniMax H3 smears her eyes and mouth, or swaps her for a stranger. This workflow fixes the face on every single frame, so the far-away shots finally look like her.
What you can do with itWide lifestyle shots that look like her. Beach, rooftop, street, gym: the whole scene in frame, her face still sharp.
Walk-up shots. She starts far away and walks to the camera, and her face holds up the whole way.
Talking from across the room. She can say her line from far away and the mouth still follows the audio.
Same girl in every clip. Your portrait reference locks her face, so a whole feed of videos stays consistent.
Extra HD. A two-pass render with a latent upscale for more detail than a single pass.
Members get the workflow, a gallery of before and after video examples, the exact prompts behind every one, and my tips for getting clean faces on the first try.
Everything you need is inside the workflow. Every model download link, which folder each file goes in, the custom nodes to install and step by step instructions are in the notes on the left side of the workflow. Open them, read them top to bottom, and you're set up. Update ComfyUI first: the Singularity model and the nvfp4 text encoder need a recent build with native MiniMax H3 support.
Want to zoom in? The full-size screenshot is attached to this post as well.
How to use it, step by stepThis one has more moving parts than my other workflows, so here's the whole run, in the order you'll touch things. The numbers on the screenshots match the steps.
Load your two refs. Drop them on the Fantastic H3 Media Loader: the close-up portrait first, then the full-body shot in the outfit and place you want. The order in the loader is the number in your prompt, so the portrait is <Picture 1> and the body shot is <Picture 2>. Drag them around to change it.
Paste your prompt into POSITIVE PROMPT. Start it with r34l1sm and write it in MiniMax's reference format. The easiest way is to copy one of my prompts below and swap the scene.
Set the length and size. VID LENGTH is in seconds; the frame count is worked out for you. LOW RES PASS (0.4 MP) and HIGH RES PASS (1 MP) set the aspect ratio. Keep both on the same ratio.
Pick turbo or quality. TURBO LoRA ON LOW RES PASS on true runs the first pass in 6 fast steps. False runs it with no turbo at 20 steps: slower, full base model quality. The high res pass always uses the turbo.
Leave the LoRA stack as it is. Only People Realism is on, at 0.8. Better Motion and Facial Realism are there, switched off. Turning them on pulls her face away from your refs and makes fast props smear.
The turbo LoRA (v4 EMA) runs both passes at 1.0. If you ever swap it, set the Sigma Shift to whatever the new LoRA's author recommends.
Face Refine runs by itself after the main render. Double-click the node to open its settings. The one dial worth knowing is DENOISE (0.40). If her face barely changes, raise it a little. If her head starts to drift against her body, lower it.
Your results. FACE REFINED (FINAL RESULT) saves to video/MMH3_facerefine, and the same clip before refine saves to video/MMH3_facerefine_orig. The BEFORE vs AFTER player shows both side by side so you can check the fix; it's a preview and isn't saved.
How it worksTwo references. Load a close-up portrait first (<Picture 1>), then a full-body shot of her in the outfit and place you want (<Picture 2>). Both are read at full size (ref_image_size = max), so H3 actually sees the details of her face.
Low res pass, then a latent upscale. The video is drawn at 0.4 MP, upscaled in latent space and finished at 1 MP. That's where the extra detail in the whole frame comes from.
Face Refine. After the render, every frame is cropped tight around her face, H3 redraws just the face at low denoise with the same prompt, refs and model, and it's pasted back with soft edges and matched color. The audio is locked, so her mouth keeps following the same line.
Both versions get saved: video/MMH3_facerefine is the final result and video/MMH3_facerefine_orig is the same clip before Face Refine. The BEFORE vs AFTER player in the workflow shows them side by side.
What's insideFantastic H3 Media Loader for your refs. Drag the order around to change which one is Picture 1.
The Singularity V2 model with the v4 EMA turbo LoRA and the AdaLN fix on both passes, 6 steps on the low res pass.
A turbo switch. On = fast 6-step low res pass. Off = no turbo, 20 steps, slower but full base model quality.
The People Realism LoRA at 0.8 on top of the turbo, the same pairing as the most realistic skin setups. Better Motion and Facial Realism sit in the stack too, switched off.
The H3 latent upscaler between the two passes.
Face Refine packed into one node at the bottom. Double-click it to open the settings.
How I made each exampleDefault settings on every one, 6 seconds each. The top zoom is the clip straight out of the render, the bottom zoom is the same frame after Face Refine. The orange box on the full shot shows where the zoom is from.
1. Smeared face, fixedShe waves from the far end of the beach, then jogs toward the camera. In the main render her eyes and mouth melt into a smear while she's small in the frame. Face Refine redraws the face on every frame from your portrait ref, so she's the same girl the whole clip, and her mouth still follows the line she says.
Refs: Picture 1 is a close-up portrait, Picture 2 is the far-away shot in the same outfit and place. Both made with Krea 2 and the same character LoRA.
Tip: Ask for a little movement toward the camera. The face grows over the clip, and Face Refine scales its strength down as the face gets bigger, so the close end stays untouched while the far end gets fixed.
The exact prompt:
r34l1sm subject_definitions: <Picture 2> is the first frame of [Shot 1], showing <Subject 1> standing far away at the edge of the water on a white-sand beach, waving at the camera. <Subject 1> is the young woman in <Picture 1> and <Picture 2>: her face, eyes, skin and hair come from the close-up in <Picture 1>, and her outfit comes from <Picture 2>, a black triangle bikini with thin straps, barefoot, bare wrists and bare ears. summary: [keyframe completion] The target video starts from <Picture 2> and shows <Subject 1> waving from the waterline of a tropical beach, calling out to the camera, then jogging a few playful steps toward it through the shallow foam. retention_analysis: <Picture 1> (identity reference for <Subject 1>): fully_preserved - the exact same face, facial structure, eyes, nose, lips, skin tone and hair as in <Picture 1>. <Picture 2> ([Shot 1] first frame): fully_preserved - the beach, the sea, the light, her bikini and her pose open the clip exactly as in the image. <Subject 1> (appears in [Shot 1]): fully_preserved - her face matches <Picture 1> and her outfit matches <Picture 2> for the whole video. detailed_description: The target video is casual vertical phone footage filmed by a friend standing still on the dry sand, bright late-morning sunlight, turquoise water, natural colours. [Shot 1] The shot begins from <Picture 2>: a static wide shot frames a long white-sand beach with footprints in the foreground and <Subject 1> small in the frame at the edge of the water, waving with a big smile. She keeps waving, cups one hand by her mouth and calls out, <d>[English] Come in, the water's so warm!</d>, then laughs and jogs a few playful steps toward the camera along the waterline, small splashes of foam around her ankles, her hair bouncing in the breeze, growing a little larger in the frame while the camera holds still. Gentle waves roll in behind her. overall_soundscape: Soft waves washing onto the sand, a warm sea breeze, distant seabirds, light splashes as she jogs through the shallow water, her voice carried from a distance with a bright laugh. non_diegetic_music: none
2. Golden hour, clean faceA wide shot across a rooftop terrace at sunset, the kind of shot every lifestyle account posts. Warm low light is where H3 usually loses the eyes. Face Refine keeps them sharp while she talks and walks.
Refs: Picture 1 is a close-up portrait, Picture 2 is the far-away shot in the same outfit and place. Both made with Krea 2 and the same character LoRA.
Tip: Keep the light on her face soft in your refs (a thin veil of cloud, golden hour). Hard midday sun on the portrait ref carries straight into the refined face as shine.
The exact prompt:
r34l1sm subject_definitions: <Picture 2> is the first frame of [Shot 1], showing <Subject 1> standing far away at the glass railing of a rooftop terrace at golden hour. <Subject 1> is the young woman in <Picture 1> and <Picture 2>: her face, eyes, skin and hair come from the close-up in <Picture 1>, and her outfit comes from <Picture 2>, a fitted black satin slip dress with thin straps and black strappy heels, bare wrists and bare ears. summary: [keyframe completion] The target video starts from <Picture 2> and shows <Subject 1> at the far end of a rooftop terrace at sunset, greeting the camera with a teasing line, then walking slowly toward it past the lounge sofas. retention_analysis: <Picture 1> (identity reference for <Subject 1>): fully_preserved - the exact same face, facial structure, eyes, nose, lips, skin tone and hair as in <Picture 1>. <Picture 2> ([Shot 1] first frame): fully_preserved - the terrace, the skyline, the warm light, her dress and her pose open the clip exactly as in the image. <Subject 1> (appears in [Shot 1]): fully_preserved - her face matches <Picture 1> and her outfit matches <Picture 2> for the whole video. detailed_description: The target video is casual vertical phone footage filmed by a friend standing still by the rooftop door, warm golden-hour light, a glowing city skyline, natural colours. [Shot 1] The shot begins from <Picture 2>: a static wide shot frames a long stone-tiled rooftop terrace with lounge sofas and olive trees in the foreground and <Subject 1> small in the frame at the far glass railing, one hand resting on it. She lifts her hand off the railing, tilts her head with a slow flirty smile and says, <d>[English] You're late... but this view makes up for it.</d>, then walks slowly toward the camera down the middle of the terrace, one foot in front of the other in her heels, the satin dress catching the warm light, growing a little larger in the frame while the camera holds still. The skyline glows behind her. overall_soundscape: A soft evening breeze on the rooftop, a distant murmur of city traffic far below, the light click of her heels on the stone tiles, her voice carried softly from a distance. non_diegetic_music: none
3. Tiny in the frame, still herShe stands behind the far baseline, a small figure across the whole court. Without Face Refine her face comes out smeared and generic. With it, the face matches your portrait ref.
Refs: Picture 1 is a close-up portrait, Picture 2 is the far-away shot in the same outfit and place. Both made with Krea 2 and the same character LoRA.
Tip: Keep small, fast props still. A flying tennis ball is one of the hardest things for H3 in a wide shot, so here the ball rests in her hand for the whole clip, and the prompt says so.
The exact prompt:
r34l1sm subject_definitions: <Picture 2> is the first frame of [Shot 1], showing <Subject 1> standing far away behind the opposite baseline of an outdoor tennis court, holding a racket and a tennis ball. <Subject 1> is the young woman in <Picture 1> and <Picture 2>: her face, eyes, skin and hair come from the close-up in <Picture 1>, and her outfit comes from <Picture 2>, a fitted white sleeveless tennis crop top, a white pleated tennis skirt, a white sun visor and white tennis shoes, bare wrists and bare ears. summary: [keyframe completion] The target video starts from <Picture 2> and shows <Subject 1> on the far side of a tennis court, holding a tennis ball still in her hand, teasing the camera, then walking up toward the net with a cheeky grin. retention_analysis: <Picture 1> (identity reference for <Subject 1>): fully_preserved - the exact same face, facial structure, eyes, nose, lips, skin tone and hair as in <Picture 1>. <Picture 2> ([Shot 1] first frame): fully_preserved - the court, the net, the fence, the sunlight, her outfit and her pose open the clip exactly as in the image. <Subject 1> (appears in [Shot 1]): fully_preserved - her face matches <Picture 1> and her outfit matches <Picture 2> for the whole video. detailed_description: The target video is casual vertical phone footage filmed by a friend standing still behind the near baseline, bright afternoon sunlight, a blue hard court, natural colours. [Shot 1] The shot begins from <Picture 2>: a static wide shot frames the blue court with crisp white lines and the low net in the foreground and <Subject 1> small in the frame behind the far baseline, holding her racket in one hand and a yellow ball resting still in the other hand, the ball staying in her hand for the whole video. She points her racket at the camera with a cheeky grin and calls out, <d>[English] Ready to lose?</d>, then laughs and walks toward the net with a confident stride, her skirt swaying, growing a little larger in the frame while the camera holds still. The green fence and trees stand behind her. overall_soundscape: A light breeze through the trees, distant birdsong, the squeak of her tennis shoes, her voice carried from across the court with a playful laugh. non_diegetic_music: none
Quick rules that save you re-rollsPortrait first. Picture 1 has to be a close-up where her face fills the frame in soft, even light. Face Refine copies this face.
Start every prompt with r34l1sm. That's the trigger word for the People Realism LoRA. Without it the LoRA barely does anything.
Use MiniMax's official reference format (subject_definitions, summary, retention_analysis, detailed_description, overall_soundscape, non_diegetic_music). Copy one of my prompts above and swap the scene.
Describe what you want, not what you don't. H3 has no negative prompt, so "bare ears" works and a "no earrings" line can backfire.
One person per shot. Face Refine fixes the largest face. For two people, run it once per person.
Face Refine helps most on small faces. On a big close-up it barely changes anything, and that's on purpose.
Short on VRAM? Lower VID LENGTH first. Full-size refs and the refine pass both add memory.
Huge credit to Carasibana for ComfyUI-H3-FaceRefine, Shrek3OnVH5 for the native audio lock node, PlagueKind for the AdaLN LoRA fix, larryvrh for the v4 EMA turbo LoRA, LBH-123-AI for the H3 latent upscaler, WarmBloodAban for Singularity V2, and the authors of the realism LoRAs (prithivMLmods, vpakarinen and fal). Links are in the workflow note.
The workflow file is attached below. Drop it into ComfyUI, read the notes, and have fun with it.
Comments (0)